Adobe’s EditAgent improves image edits at a compute cost
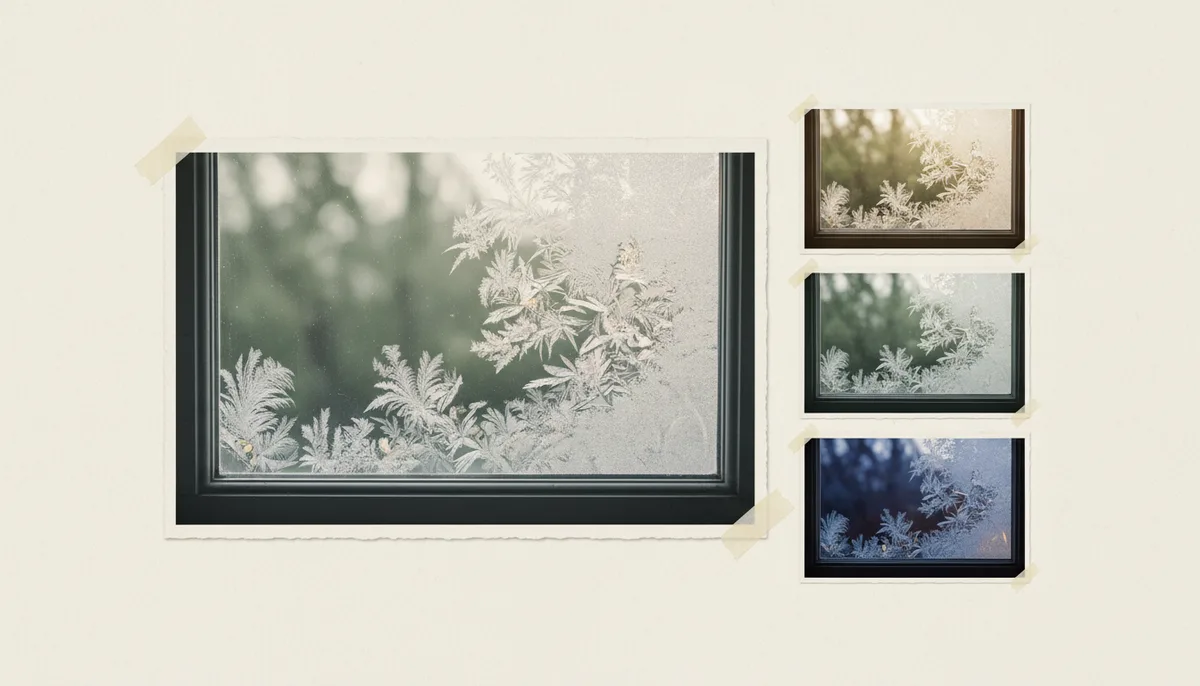
Illustration, not documentary evidence of the event.
Researchers at Adobe Research and UC San Diego built EditAgent, an image-editing agent that generates competing edits with general-purpose and specialized tools, then selects results using close-ups and measured image statistics. It outperformed seven other agents in the reported research, but required about ten times the compute of a single editor, according to the-decoder.com.
The system also checks whether later changes undo earlier instructions. In one reported example, adding daylight cleared a window that had previously been made frosted. EditAgent detected and corrected the conflict. These are research results, not evidence that Adobe’s existing creative-app agents deliver the same performance.
For teams choosing an editing workflow, the useful distinction is between generating an acceptable image and reliably selecting it. On the researchers’ 600-edit benchmark, Qwen3.8-27B selected a result professionals considered usable 81.3 percent of the time when given verification records. EditScore-72B, a model trained specifically to evaluate edits, achieved 74.8 percent. Calculated comparison: the difference is 6.5 percentage points. Across a hypothetical 1,000 selection decisions with the same success rates, that would mean 813 usable selections versus 748, or 65 more. This illustrates the reported selection advantage, not an end-to-end editing success rate or a forecast for another image collection.
That distinction gives workflow builders a concrete priority: evaluate candidate selection separately from image generation. For a constrained request such as gentle brightening, compare whether the selection process preserves acceptable brightness and color, rather than judging only whether the final image looks appealing. The research suggests that supplying relevant evidence to the judge can change the outcome: without verification records, none of the seven tested language models matched the strongest specialized evaluator; with them, all seven surpassed it.
The compute tradeoff suggests a separate decision for teams producing training data. EditAgent generated about 26,000 verified examples, and editors trained on them improved across all three reported benchmarks. Data generated directly by FLUX instead made FLUX worse. Taken together, those findings support considering the expensive agent as a training-data producer, with a faster editor handling subsequent requests. Before choosing that route, compare the cost of generating and reviewing the dataset with the resulting editor’s measured improvement on your target tasks. The report supplies no cost figures or deployment volumes from which to calculate a break-even point.